Project · ynara
Ynara
- Role
- Da Vinci Thesis 2026 · lead contributor
- Client
- Escuela Da Vinci · Buenos Aires, AR
- Year
- 2026
- Status
- In development
- Technologies
- FastAPIBackend. Since 2026. The core for AI/NLP inference and processing, with Pydantic typing and minimal latency. Also in Eros Career OS.
- Next.jsFrameworks. Since 2026. A full-stack React framework with asset optimization, file-system routing and SSR. Also in Ynara Web.
- PostgreSQLData. Since 2026. ACID relational persistence, declarative schemas and vector indexes with pgvector. Also in Eros Career OS.
- PythonLanguages. Since 2026. The language of choice for data engineering, vector embeddings and LLM orchestration. Also in Eros Career OS.
- ReactFrameworks. Since 2026. A massive ecosystem, React Server Components and hybrid rendering, adopted in the Ynara thesis. Also in Barberpole and Ynara Web.
- TypeScriptLanguages. Since 2023 · 3 years. A mandatory standard on client and server: if it isn't typed at compile time, it doesn't reach production. Also in Ynara Web and Eros Career OS.
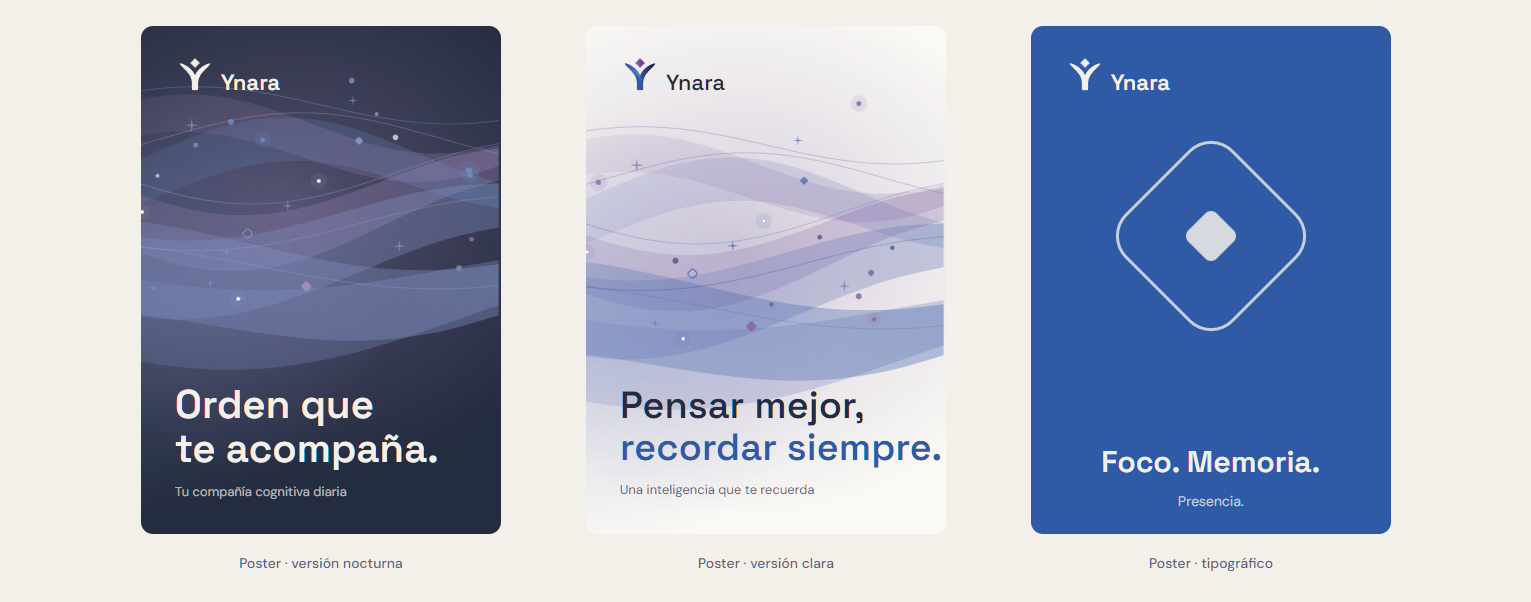
Team thesis, pre-approved. An adaptive, on-prem personal AI assistant with encrypted semantic, episodic and procedural memory on Postgres and pgvector.
Brief
An assistant that runs on your machine, talks like you and remembers. Dual LLM (Gemma and Qwen via Ollama), its own encrypted three-layer memory, and a FastAPI, Next.js and Expo monorepo.
Process
Hypothesis
Cloud assistants sacrifice privacy and local context. The hypothesis: an on-prem model with vector memory can be faster, more private and more natural.
Architecture
A monorepo with FastAPI orchestrating embeddings and calls to Ollama; PostgreSQL 17 with pgvector for cosine similarity search; Next.js 14 for the web front end and Expo for mobile.
Result
Contextualized answers with under 50ms of internal query latency and 100% encrypted local storage.
Outcome
Thesis pre-approved with commendation at Da Vinci. 382 commits leading the backend architecture, the vector database and the local inference engine.
Metrics
- 382CommitsCommits. Changes recorded in the repository during development.
- Gemma 2B · Qwen 2.5Local modelsLocal models. Language models that run on the machine, without external services.
- 48 msLatencyLatency. Average response time of a query.
- 3Encryption layersEncryption layers. Encryption layers that protect the stored data.
- 1,536DimensionsDimensions. Dimensions of each vector in the semantic memory.